Abstract
Recent studies suggest that pre-trained large language models (LLMs) might develop distinct functional roles across their layers: early layers focus on understanding the input context, middle layers handle task-specific processing, and late layers map abstract representations to output tokens. Inspired by the intuition that humans can produce an extended sequence of speech from a single act of reading and thinking, we hypothesize that a single pass through the early and middle layers could provide sufficient information to support the decoding of multiple future tokens. Accordingly, we propose Direct Multi-Token Decoding (DMTD), which performs only one full forward pass for every n tokens and reuses the late layers to decode multiple subsequent tokens. Unlike speculative decoding, our method introduces no additional computation, auxiliary routines, or post-generation verification. With minimal training overhead, a Qwen3-4B model finetuned with DMTD achieves up to a 2.15× speedup with marginal performance loss, and our scaling analysis indicates that its performance could be further improved with larger-scale training.
Main Idea
In our previous work FlexiDepth, we discovered that pre-trained large language models contain redundancy, as many layers can be skipped without affecting performance. However, these layer-skipping patterns are irregular and difficult to provide acceleration in memory-bound scenarios. DMTD repurposes this redundancy into a regular pattern by cyclically reusing the late layers to efficiently generate multiple tokens. Importantly, DMTD introduces no additional parameters, auxiliary routines, or post-generation verification like speculative decoding.
DMTD is also compatible with speculative decoding. Since a DMTD model can generate several tokens in one cycle, it can serve as its own fast drafter and then verify the drafted tokens with the full DMTD model. We provide a DMTD Qwen3-4B model with several decoding variants, including DMTD, DMTD with speculative decoding, tree speculative decoding, and Medusa-style tree speculative decoding.
Architecture
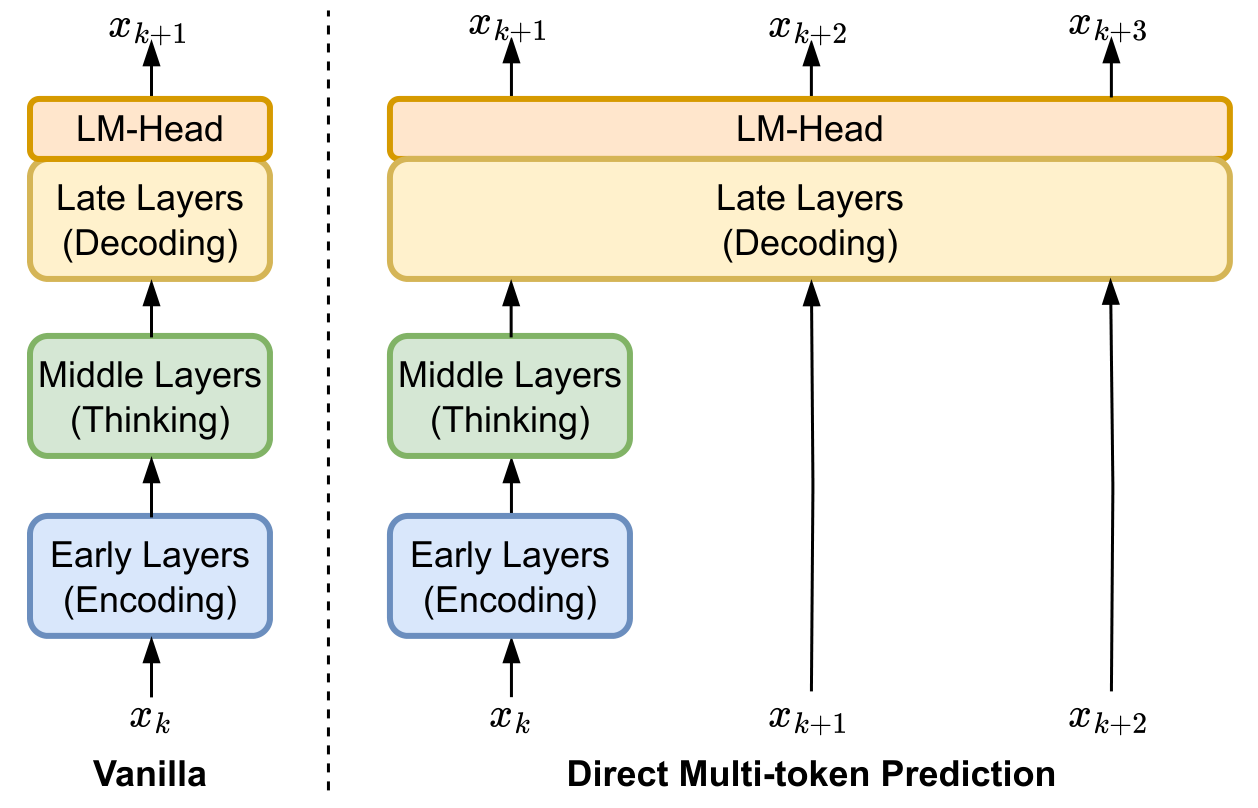
Unlike the vanilla decoder-only transformer that generates tokens one by one through full forward passes, the proposed DMTD operates in fixed multi-token cycles. Figure 1 (right) demonstrates the generation pipeline of DMTD in a single cycle. DMTD performs only one full forward pass at the beginning of the cycle and then reuses the later layers to decode multiple tokens consecutively. This cycle-based setting transforms the irregular computational redundancies observed in pre-trained LLMs into a fixed periodical pattern for efficient decoding.
Connection to Looped Transformers
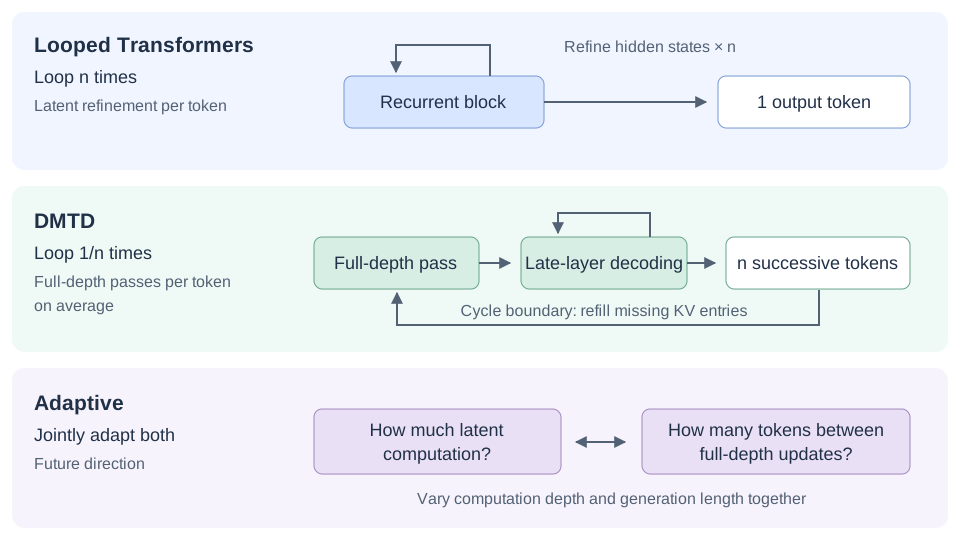
Looped Transformers increase computational depth by repeatedly refining hidden states before predicting the next token. DMTD explores a complementary direction: one full-depth pass supports several successive token predictions through the late layers, with missing early- and middle-layer KV entries refilled at cycle boundaries. Both perspectives relax the fixed coupling between full-depth processing and token generation. This suggests a future direction: jointly adapting how much latent computation to perform and how many tokens to generate between full-depth updates.
Scaling with Training Data
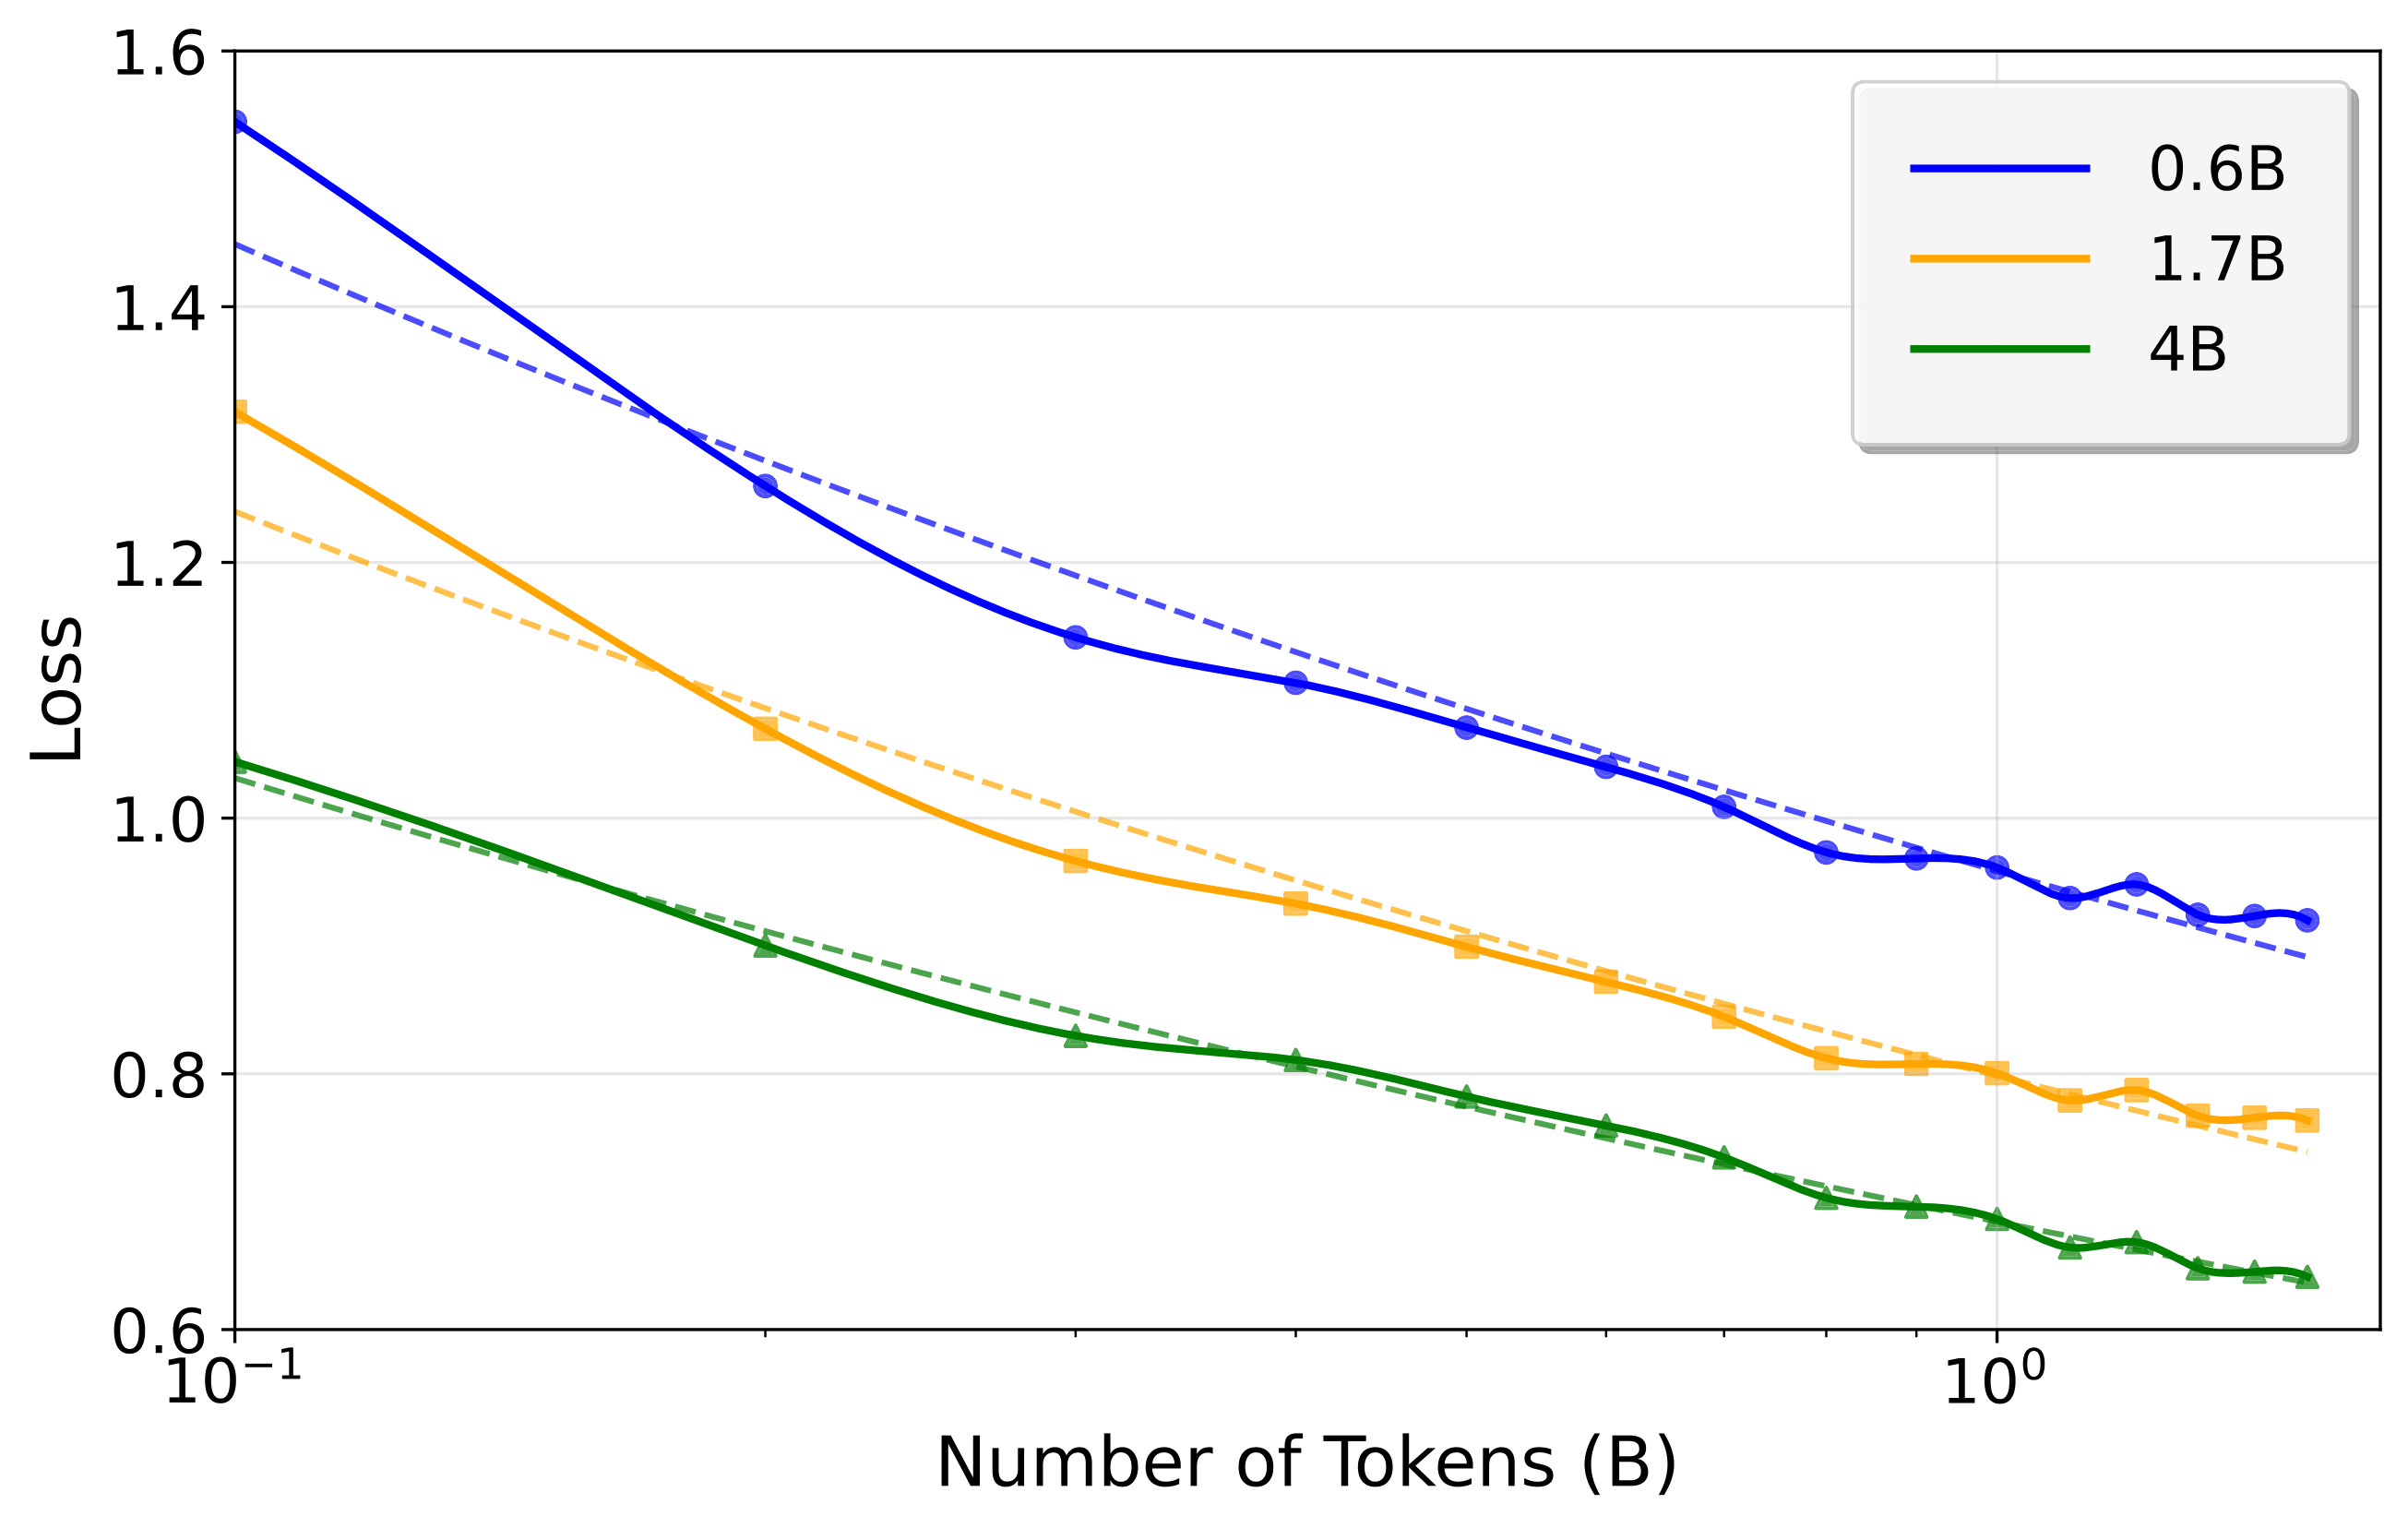
We conducted scaling experiments to understand how DMTD's performance improves with increasing training data across different model sizes (0.5B, 1.5B, 3B, 7B, and 14B parameters). The results reveal a consistent decrease in cross-entropy loss as training data increases for all model sizes, with the trends approximating log-linear relationships. Our current training uses only 1.5B tokens with a 4K context length. With large-scale continued pre-training, the performance of our method is expected to further improve, potentially enabling each cycle to decode more tokens efficiently. Training with longer contexts and reinforcement learning (RL) may also help further improve performance; these remain directions for future exploration.
Results
We evaluate our method by reusing the last 8 layers of Qwen3-4B, where Cτ denotes a decoding cycle of τ tokens. Across six benchmarks, C2 and C3 achieve 100.9% and 99.4% of the vanilla model's overall performance, respectively, while C4 retains 95.9%. Extending the cycle to C6 reduces overall performance to 81.7%, illustrating the trade-off between cycle length and prediction quality.
| Model | ARC-E | ARC-C | WinoGrande | GSM8K | CoQA | MBPP+ | Overall |
|---|---|---|---|---|---|---|---|
| Vanilla | 0.934 | 0.922 | 0.657 | 0.907 | 0.805 | 0.669 | 100.0% |
| C2 | 0.930 | 0.897 | 0.701 | 0.901 | 0.798 | 0.693 | 100.9% |
| C3 | 0.921 | 0.886 | 0.673 | 0.889 | 0.780 | 0.698 | 99.4% |
| C4 | 0.916 | 0.881 | 0.652 | 0.866 | 0.749 | 0.627 | 95.9% |
| C6 | 0.872 | 0.801 | 0.601 | 0.500 | 0.672 | 0.536 | 81.7% |
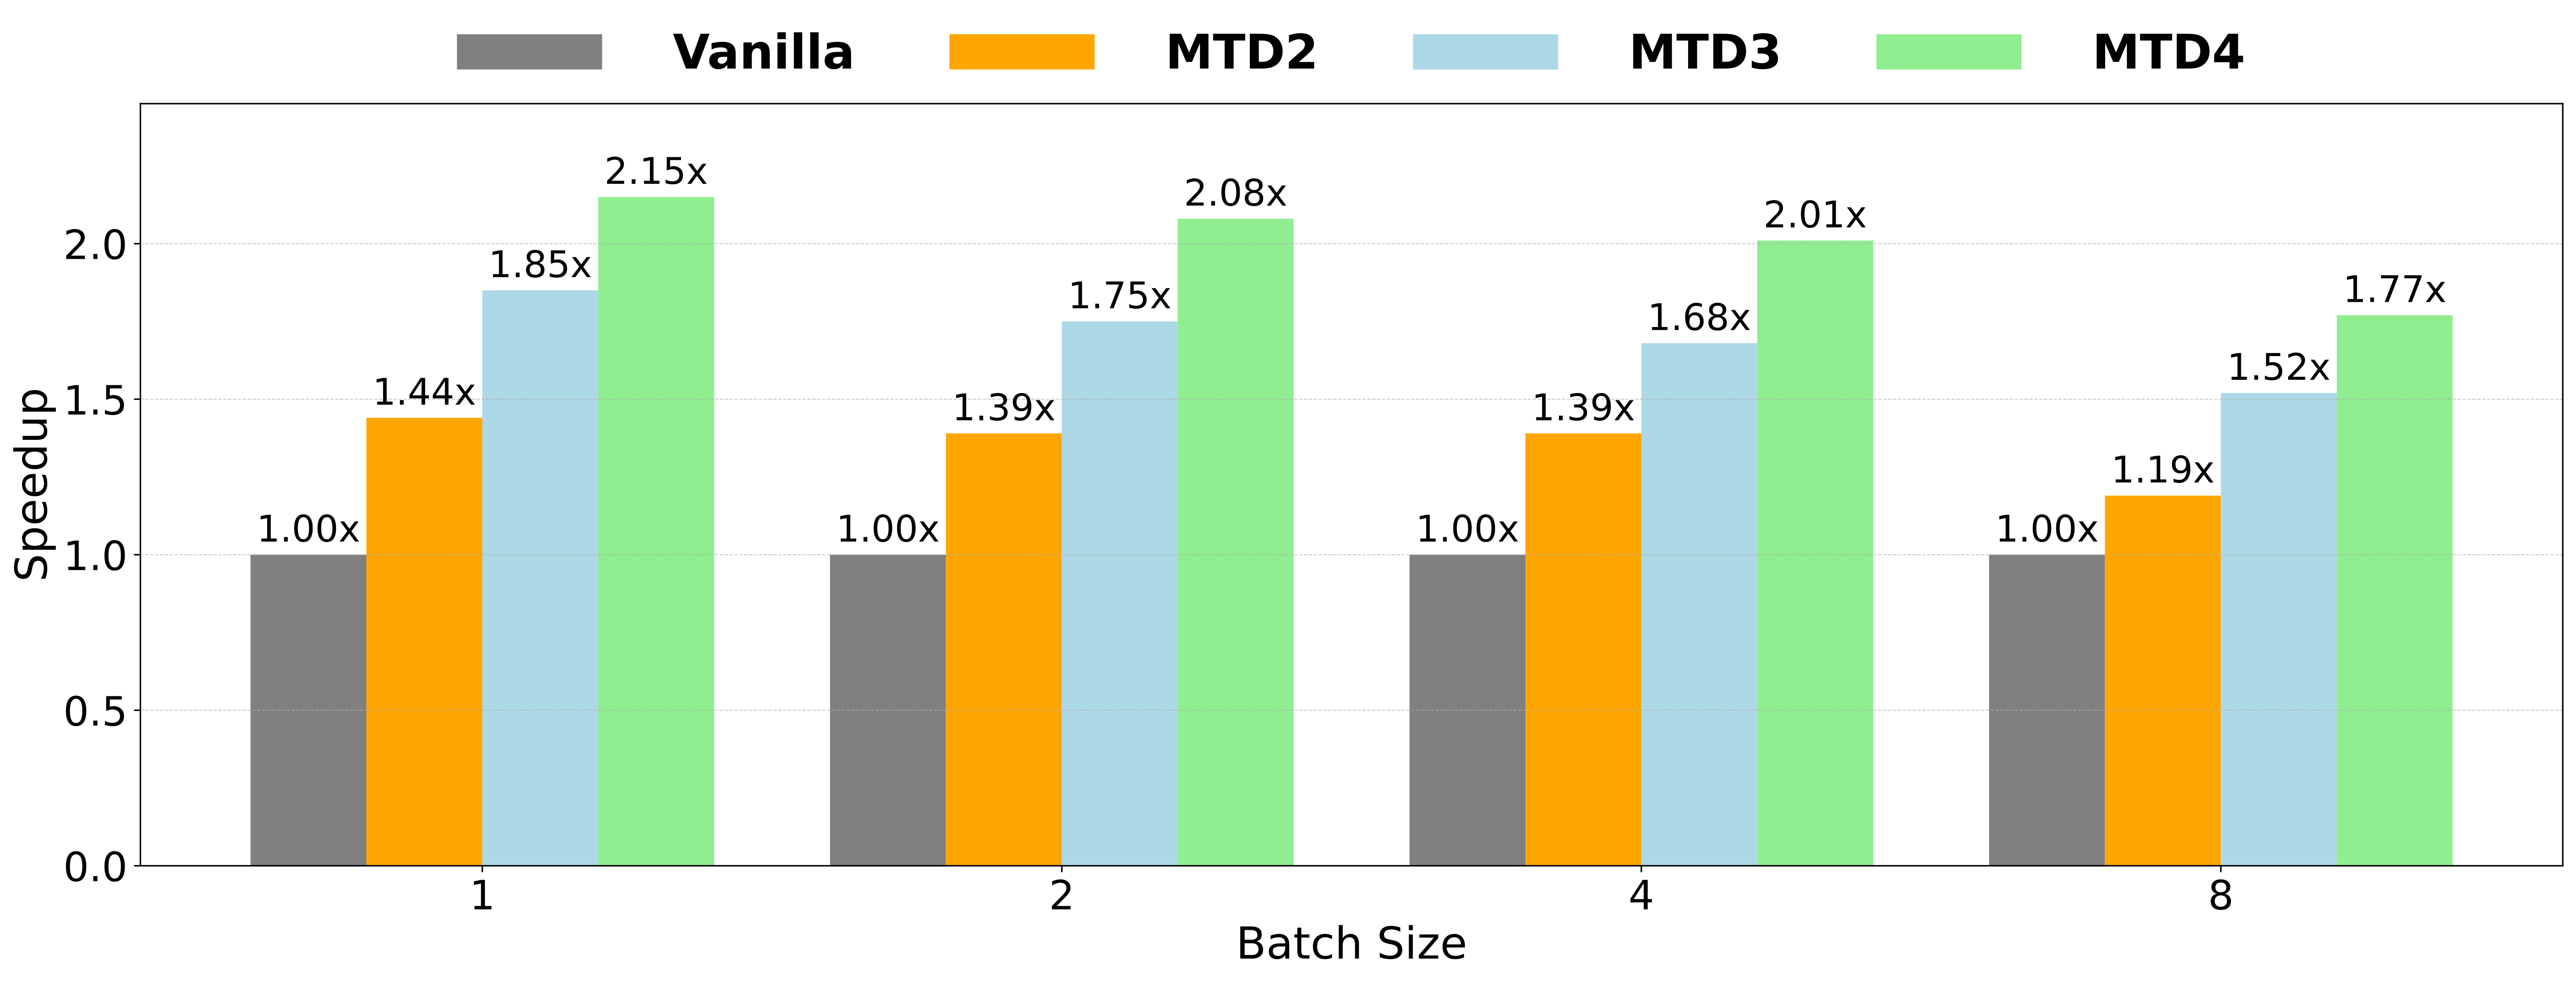
Our method achieves up to 2.15× speedup when generating 4 tokens per cycle (C4), while retaining 95.9% of the vanilla model's overall benchmark performance. DMTD does not rely on speculative decoding, but it is orthogonal and complementary to speculative decoding techniques. The plain DMTD results shown here can therefore be further combined with self-speculative variants implemented in the released model.